ai
How Many People Can Share One H100 Running an In-House LLM?
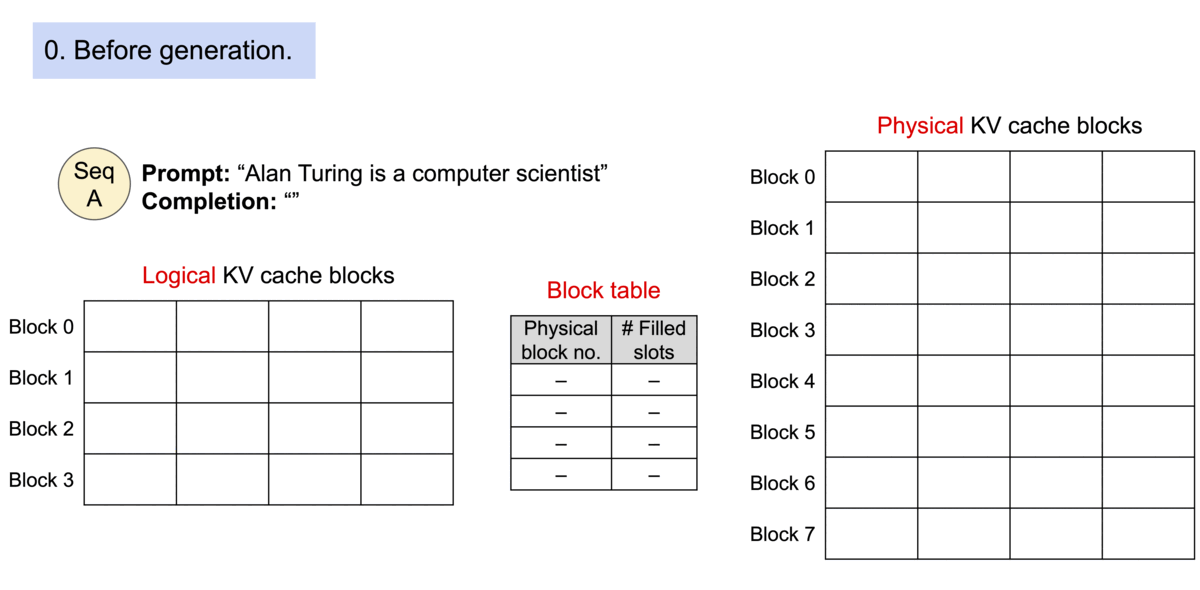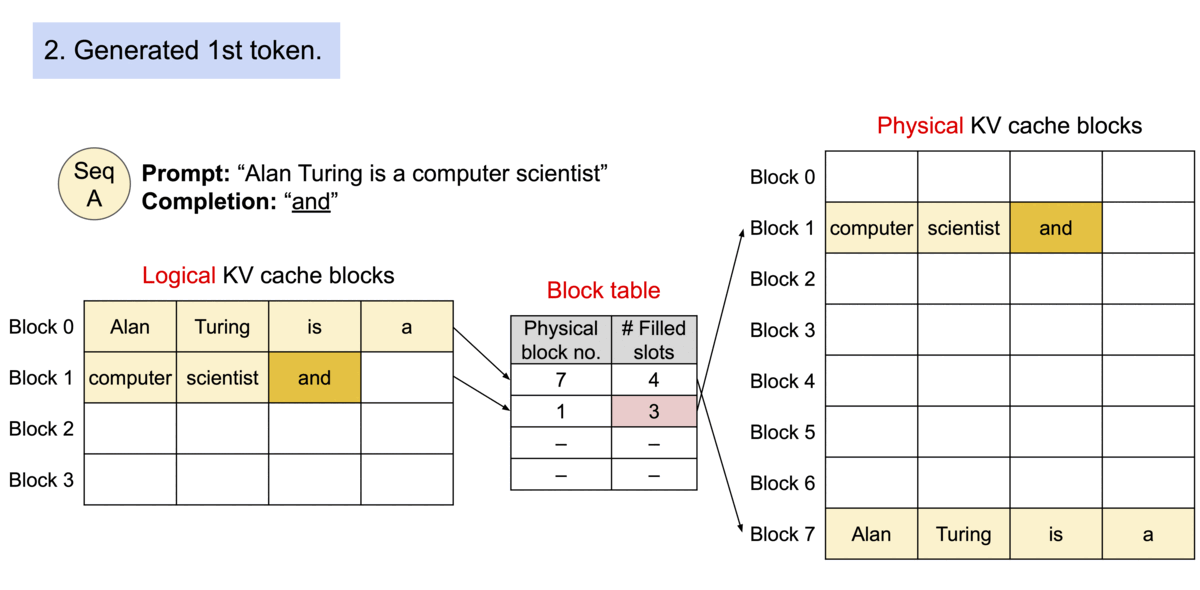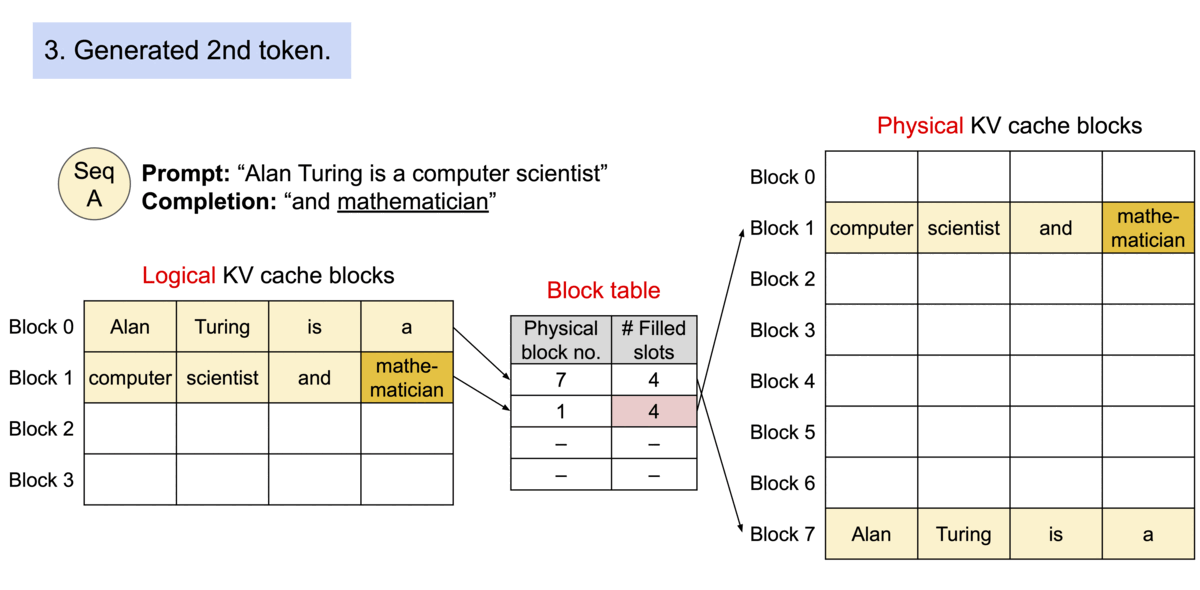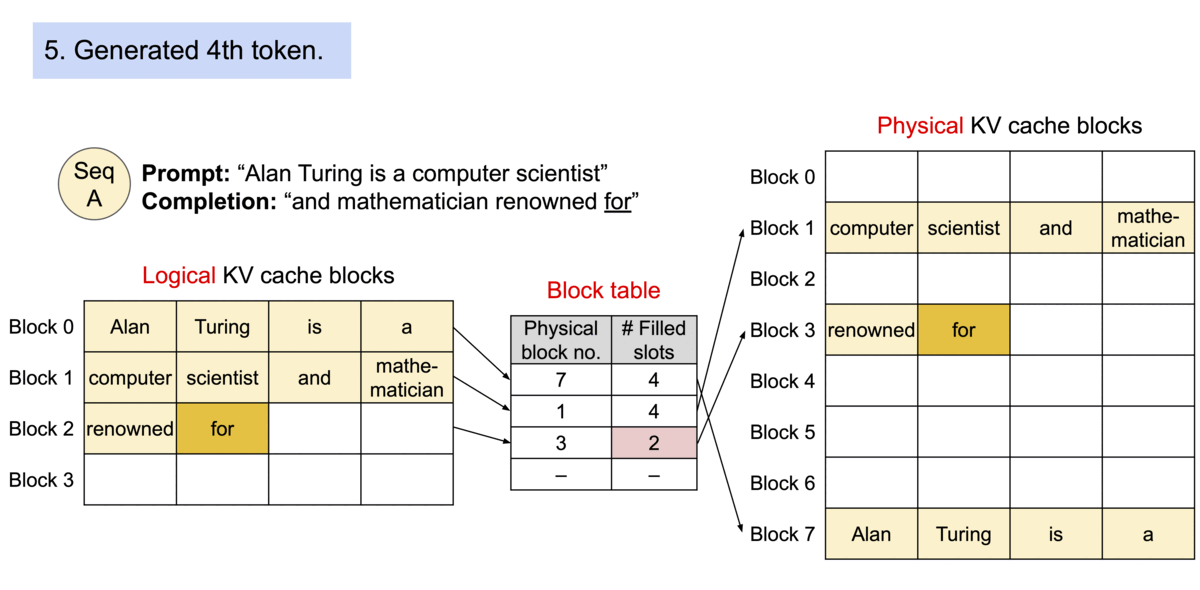
If you know the size of the model weights and the KV cache, you can estimate quite closely how many requests one GPU can hold at once. We worked it out for Qwen3-32B on an H100 80GB.
Read More→